The 8 GB Lab Book · Chapter 1
There is no VRAM on this board
- Board
- Jetson Orin Nano Super
- Mode
- 15W (nvpmodel 0)
- Summary
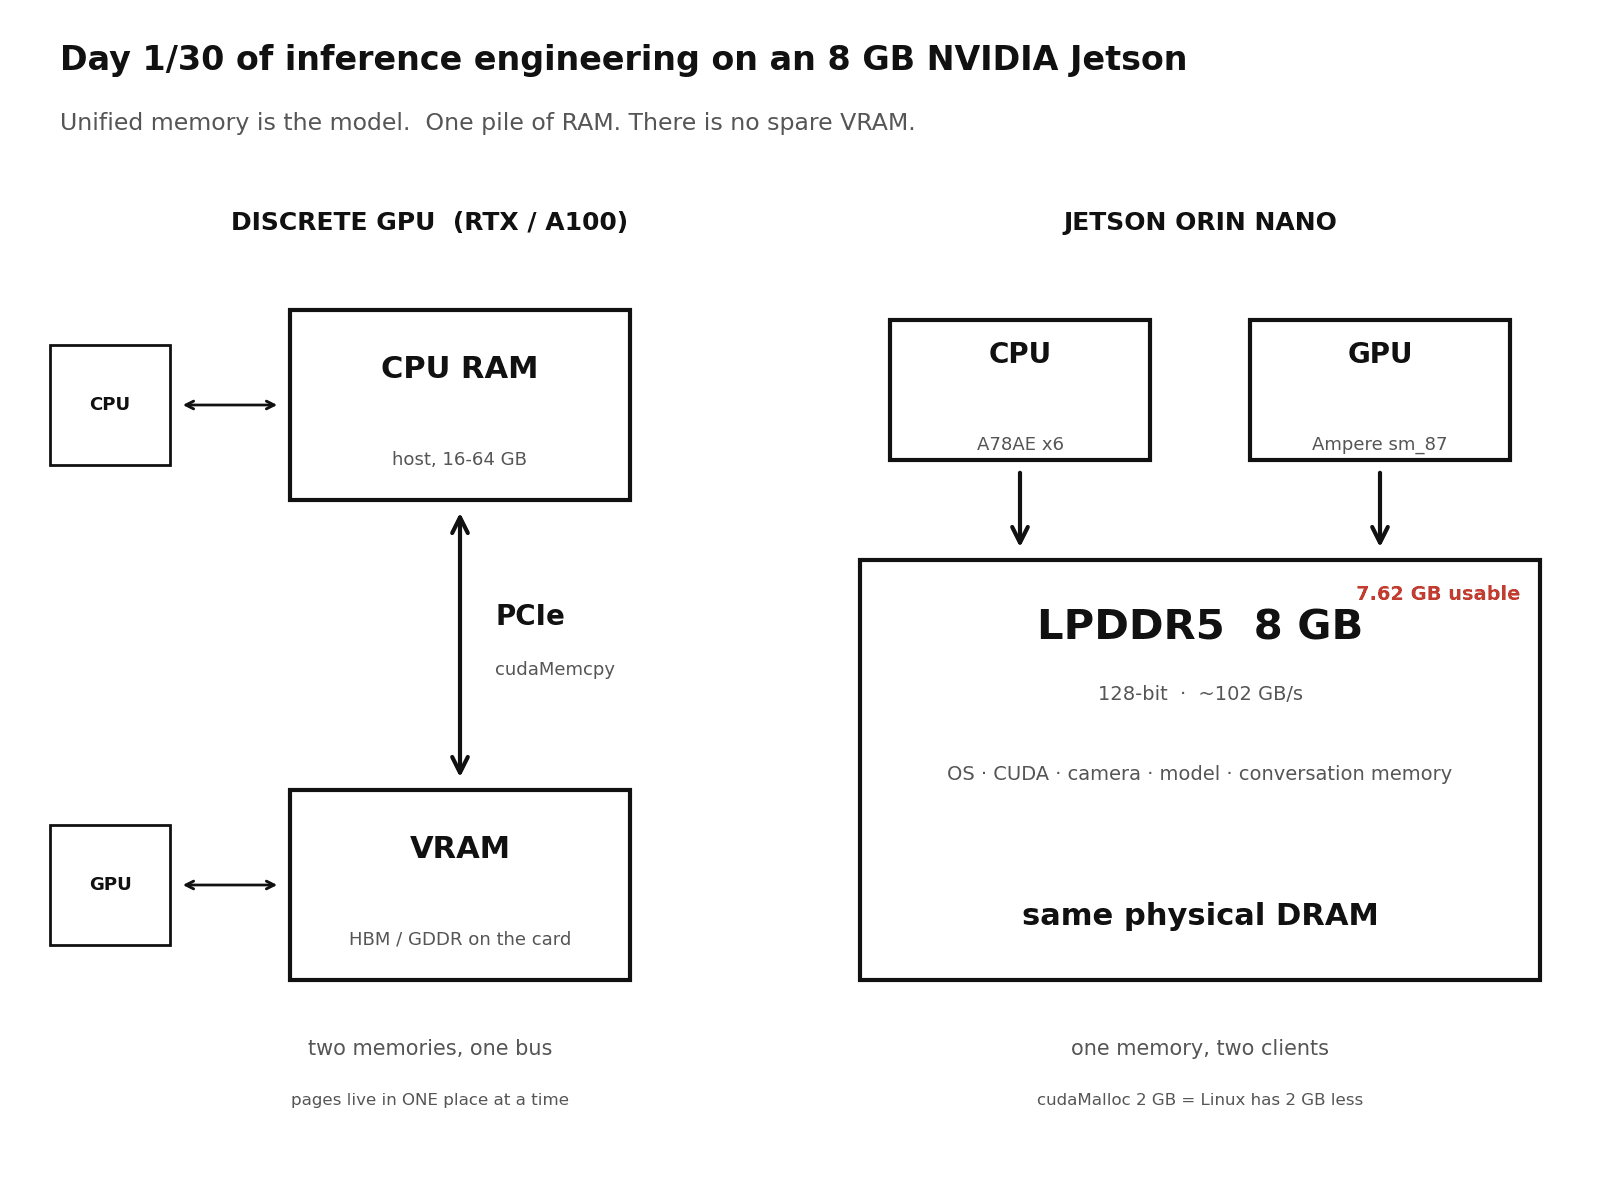
- The board shows 7,620 MB of one shared pool, not 8,000. The 7B plus the 3B reached 7,441 MB, and swap took 659 MB more. The model load deltas subtract the 643 MB idle of that run.
What I expected
Before the run, I wrote down each expected cost.
- Usable memory: 8,000 MB
- CUDA context, cudaFree(0): ~800 MB
- CUDA context, torch: ~800 MB
- Llama-3.2-1B Q4_K_M: 700 MB
- Llama-3.2-3B Q4_K_M: 1,800 MB
- Qwen3-4B Q4_K_M: 2,250 MB
- gemma-3n-E2B Q4_K_M: ~3,000 MB
- Qwen2.5-7B Q4_K_M: 4,300 MB
- 7B + 3B together: 8,000 MB (my note; the 7B and 3B rows above sum to 6,100)
The theory
Why there is no vram here
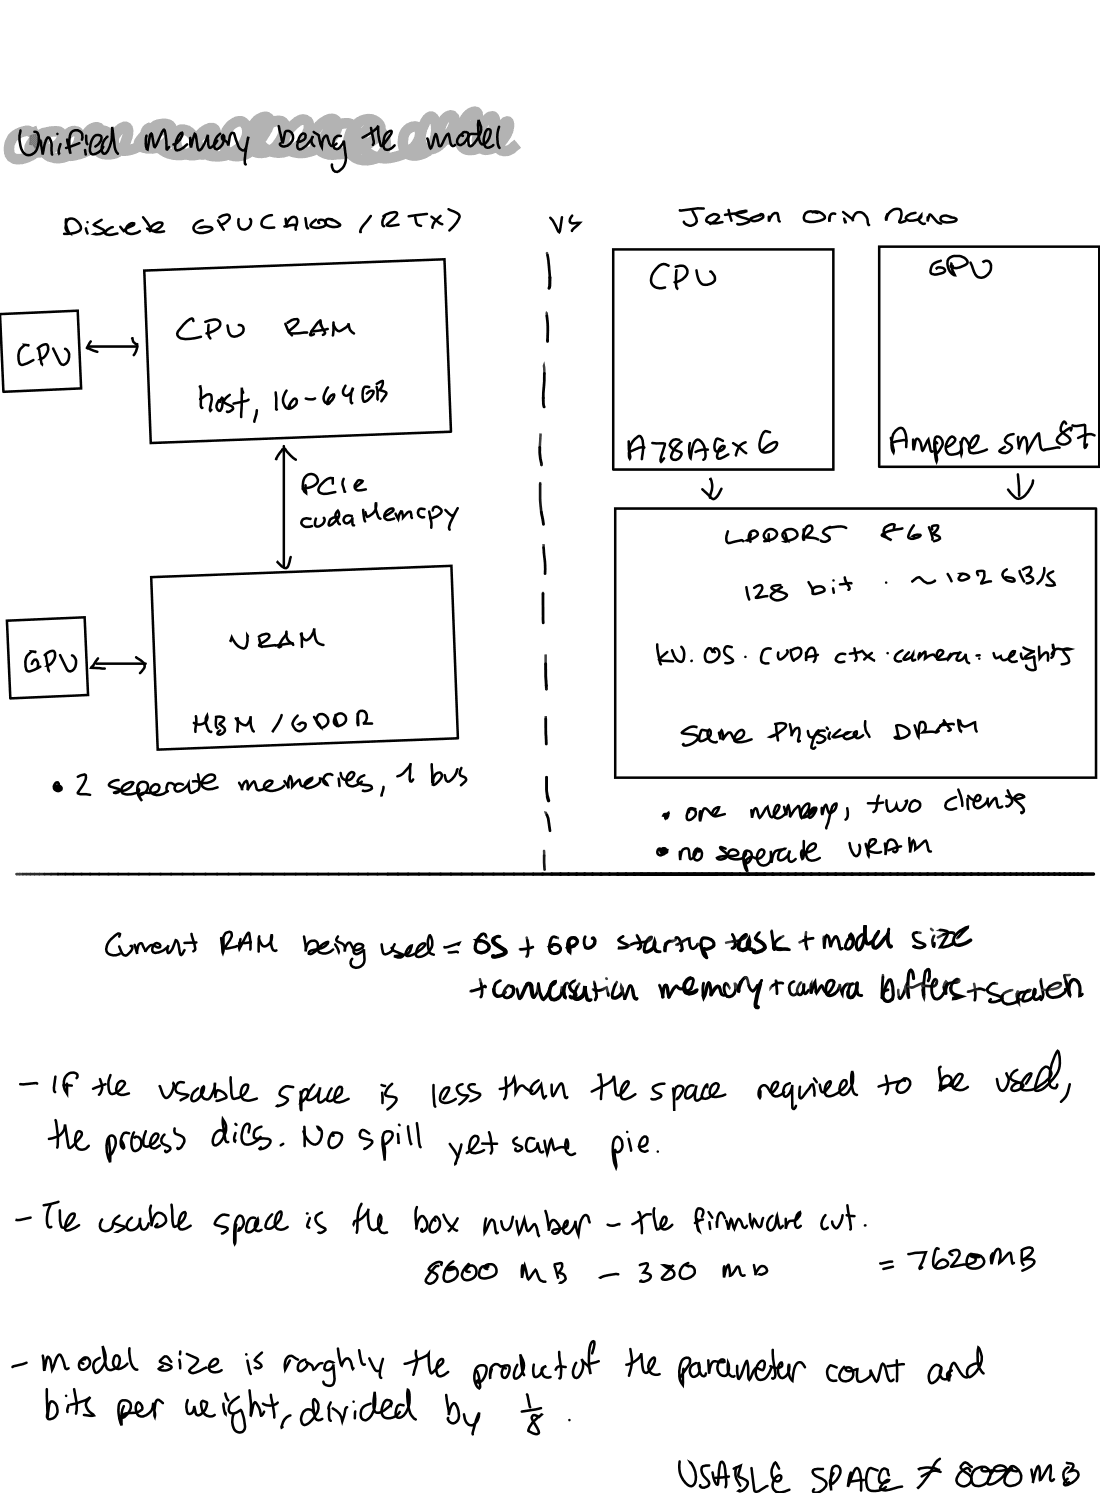
A normal PC keeps the model weights in VRAMDedicated memory attached to a discrete graphics card; a Jetson has none, so GPU buffers come out of the same system RAM as everything else.. VRAM is a separate chip on the graphics card. The OS runs in its own separate memory.
This board does not have this division. The OS, CUDA, the camera and the LLM all use memory from one 8 GB chip. There is one pool, not two pools.
THE ARITHMETIC: how close a call the 7B+3B was
7620 visible - 7441 resident (7B+3B) = 179 MB. This is the headroom that remained.
Then swapDisk or compressed-RAM space the kernel uses to hold memory pages when physical RAM runs short; touching a swapped-out page is slow. increased by another 659 MB in addition to that. There was no location where it could go.
7620 - 5355 (7B alone) = 2265 MB is still free with the 7B resident. The 3B alone took 3109 MB, more than this margin. So the second model does not fit. It left 179 MB and pushed 659 MB into swap.
The measurement
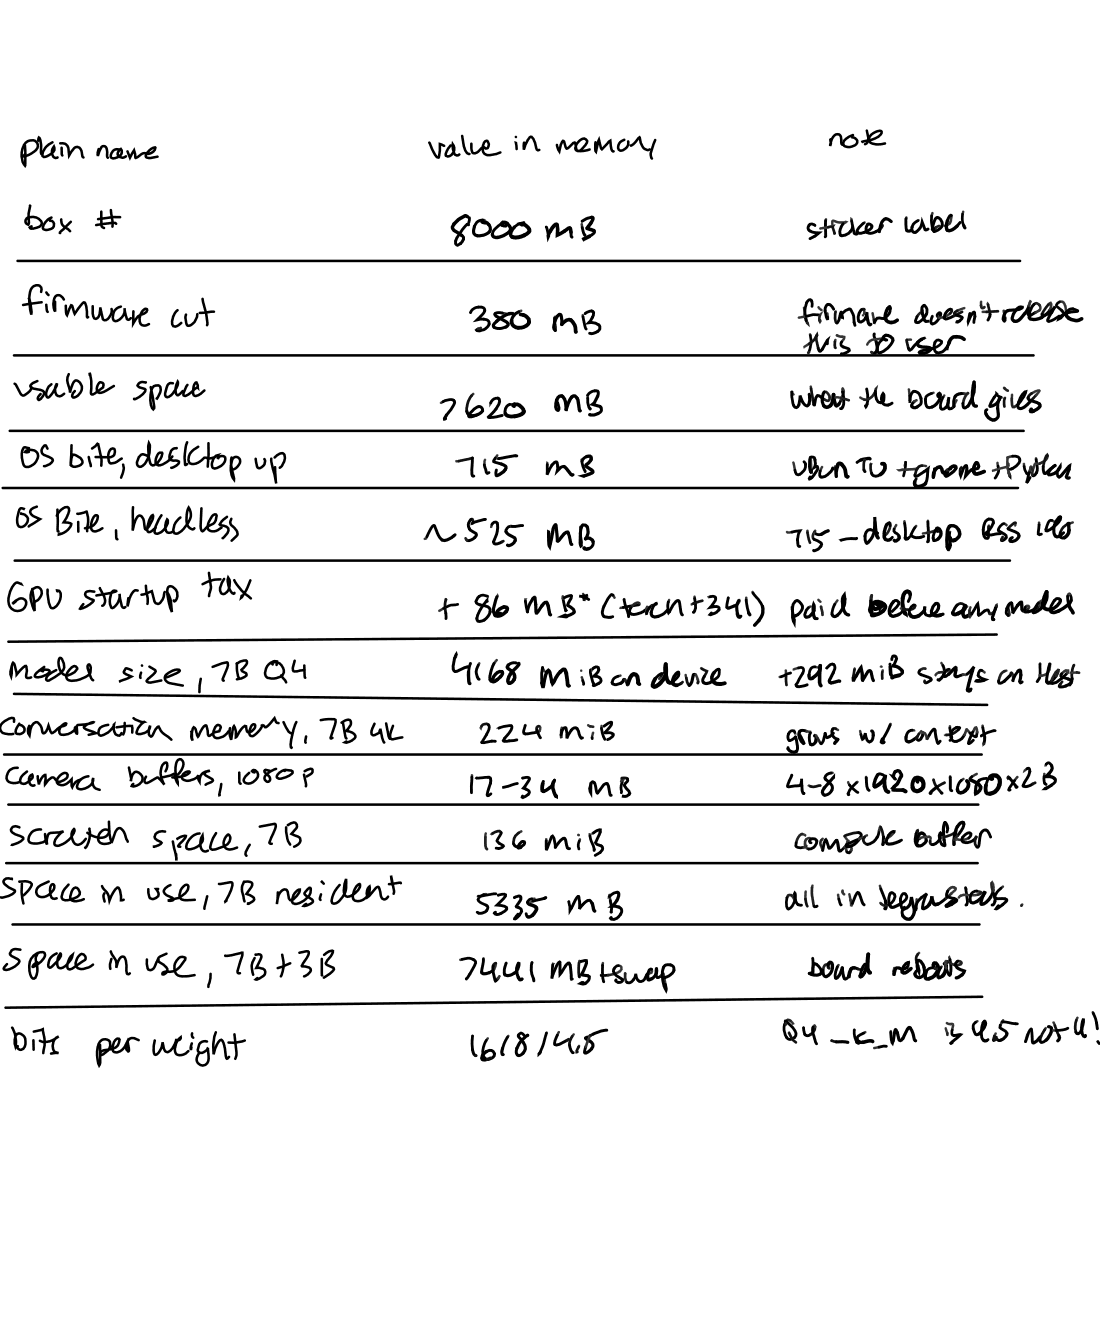
| What | Expected | Measured | Note |
|---|---|---|---|
| Usable memory | 8,000 MB | 7,620 MB | 8192 - 7620 = 572 MiB reserved below Linux |
| Idle, desktop up | - | 715 MB | desktop idle (measured.json). The two CUDA rows subtract 715. The six model rows subtract 643, the idle when the loads began |
| CUDA context, cudaFree(0) | ~800 MB | +86 MB | |
| CUDA context, torch | ~800 MB | +341 MB | torch libraries + context |
| Llama-3.2-1B Q4_K_M | 700 MB | +1,441 MB | pile 2084 · dev 955 MiB |
| Llama-3.2-3B Q4_K_M | 1,800 MB | +3,109 MB | pile 3752 · dev 2436 MiB |
| Qwen3-4B Q4_K_M | 2,250 MB | +3,622 MB | pile 4265 · dev 3031 MiB |
| gemma-3n-E2B Q4_K_M | ~3,000 MB | +3,421 MB | pile 4064 · N from file size |
| Qwen2.5-7B Q4_K_M | 4,300 MB | +4,712 MB | pile 5355 · dev 4528 MiB |
| 7B + 3B together | 8,000 MB (rows sum to 6,100) | +6,798 MB | 7441/7620 + swap 659 -> reboot |
What's on the GPU, one model (7B)
Qwen2.5-7B, on device
weights          4168 MiB
KV cache          224 MiB
scratch           136 MiB
= = 4528 MiB on the GPU
The remainder of the 5355 MB pile is 827 MB. It is on the CPU side: page cache, buffers and python.
With torch, it costs 341 MB only to start CUDA, not 86. The runtime that you select is a part of the budget.
I measured these numbers on the board with tegrastatsNVIDIA's Jetson monitoring tool, which prints RAM, swap, CPU and GPU load, clock speeds, temperatures and power readings at a fixed interval. at 15W, with the desktop on.
The fixed costs before any model loads
the fixed costs, MiB (tegrastats labels them MB)
- 8 GB chip
- 8192
- visible
- 7620
- idle
- 715
- CUDA ctx
- 86
- reserved
- 572
The board gave visible, idle and CUDA ctx while it ran. tegrastats prints MB, but it counts MiB vs MBA mebibyte (MiB) is 2^20 bytes and a megabyte (MB) is 10^6 bytes; some tools label MiB as "MB", so check which one a tool actually counts.. The 8 GB chip is 8192 MiB. So 8192 - 7620 = 572 MiB is reserved before Linux counts it. My first note gave 380 MB, but that was 8000 - 7620, a subtraction across two units.
Six loads, climbing to the wall
Line at 7620 ceil
| model | predicted | measured |
|---|---|---|
| 1B | 700 | 1441 |
| 3B | 1800 | 3109 |
| 4B | 2250 | 3622 |
| E2B | ~3,000 | 3421 |
| 7B | 4300 | 4712 |
| 7B+3B | 8000 (rows sum to 6100) | 6798 |
Where it broke
I predicted 700 MB for the 1B and measured 1441. Every model cost more than my note, the 1B twice as much, because I had counted weights and not the context, the scratch and the runtime. The 7B plus 3B did not reach my 8,000 prediction. It reached 7,441 MB, then 659 MB of swap, then a reboot. My 8,000 was not even the sum of my own rows, which is 6,100.
My notes from Day 1
Written by hand on 2026-09-01, before this chapter was typed. These are my original notes from that day. Where the chapter corrects them, the chapter is current.
Summary
- The sentence "4B Q4 only needs 2.5 GB of VRAM" is dimensionally wrong on this board. That sentence assumes that a 16 GB host is next to the card. On Nano, the 2.5 GB, the CUDA context, the camera pool and Ubuntu are parts of one pool.
- OOM is not a CUDA error that you catch and then try again on host RAM. There is no host RAM. First the pile becomes full. Then the board fails.
- Make the budget from the measured idle. Do not use the 8,000 on the sticker.
Sources
These sources are not mine. Measured numbers came off my own board; specs, estimates and paper figures are labeled as such.
- NVIDIA CUDA programming guide (UM vs copy)
- Jetson architecture: iGPU + shared LPDDR5
- NVIDIA Developer Forum on pinned vs device buffers on Orin (pinned ≠ always fastest)
- Jetson Orin Nano 8GB datasheet: 8GB 128-bit LPDDR5, 102 GB/s in Super